Automation and Agents
Agent-Native 0.187: Check Interrupted Writes Before Retrying
When an agent loses a write response, the destination may already have changed. A source-based guide to reconciling the action before retrying.
On this page
- What changed when a run aborts
- Find the attempted action before inspecting its result
- Separate confirmed effects from unresolved outcomes
- A request identifier is not the same as retry safety
- Read the narrower retry promise carefully
- Plan an interruption test that can answer the right question
- Check what a resumed workflow is allowed to do
- Make the recovery handoff usable for another person
- Decide which workflow to evaluate first
A support ticket may already exist even when your agent never receives a reply. If its write is interrupted, check the destination before retrying. The next step depends on what happened there, not on the last line in the chat.
Imagine a request that reaches the support service just before the agent loses its connection. You still need the ticket. Sending another create request could finish a missing job, or create a duplicate of work that already happened.
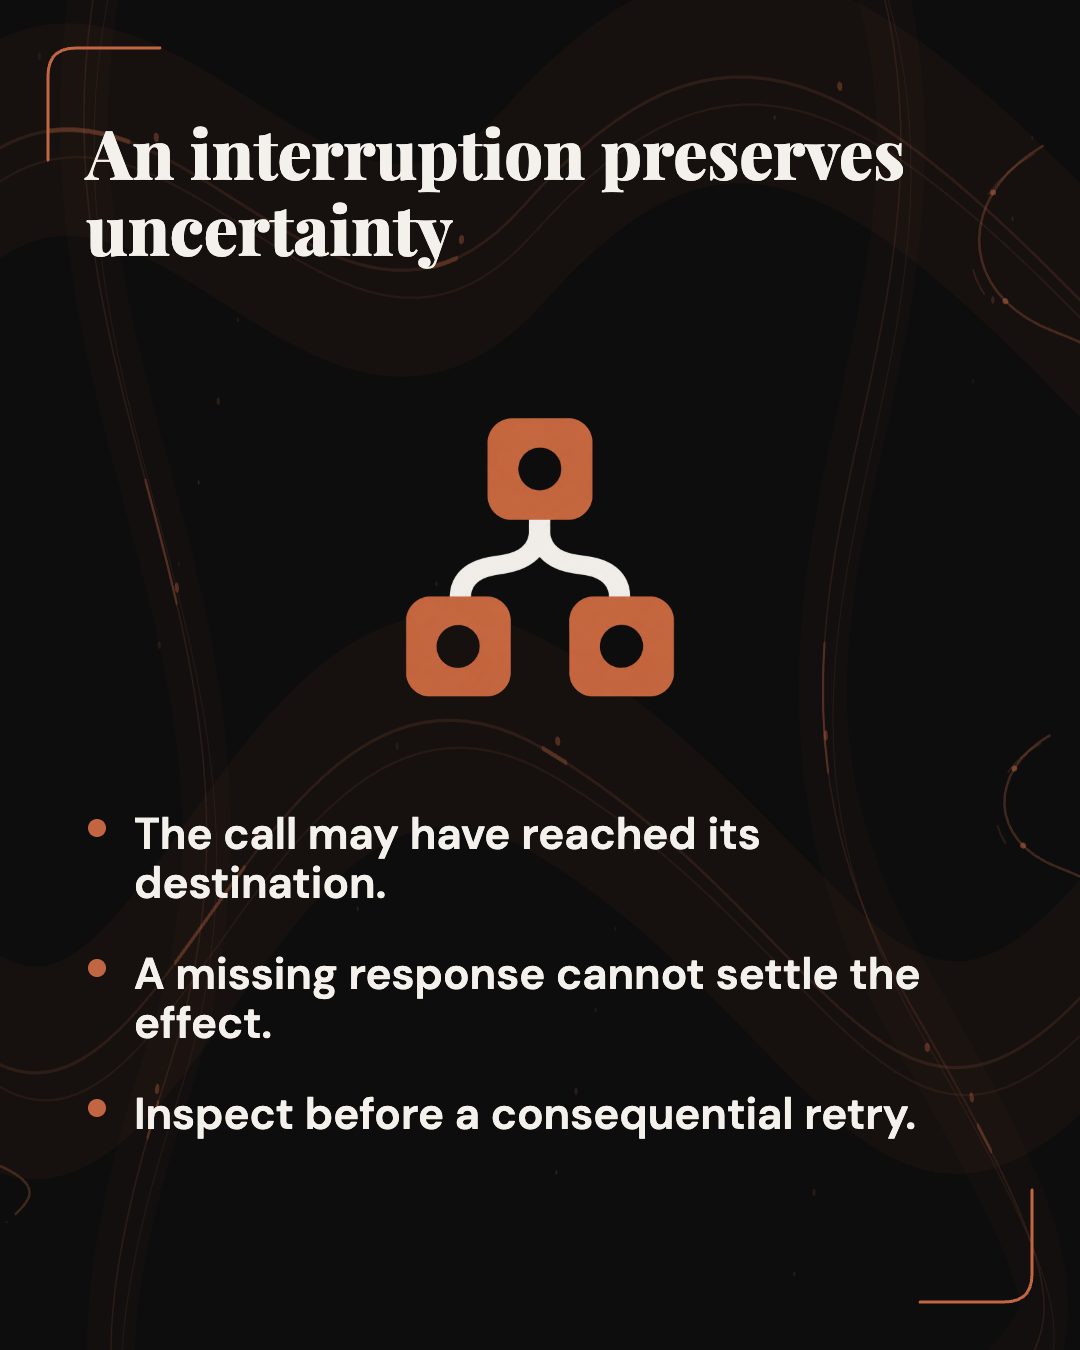
Agent-Native 0.187 changes how Builder.io says its runtime records that interruption. A tool call stopped by a run abort becomes an unknown outcome, rather than an ordinary failure. The practical response is to check what happened at the destination before deciding whether to repeat a consequential write. A missing response cannot settle that decision.
Builder.io published the core 0.187 release on September 24, 2026, as confirmed by its GitHub release record. This article examines that release and the original change behind it. The support scenario and evaluation below are proposed examples, not a test of an Agent-Native deployment.
Key takeaways
- An interrupted write can have an unknown outcome even when the agent receives no usable result.
- Agent-Native's change preserves that uncertainty for recovery. It does not prove what an external service did.
- Match the attempted action to destination-side evidence before retrying. An operation identifier helps only when the destination can use it.
- Test the exact integration and failure boundary with disposable data before allowing automatic retries on important work.
What changed when a run aborts
The original interrupted-tool change explains the bug Builder.io was addressing. The runtime had recorded an aborted call as an ordinary error. A resumed chunk could then read that result as evidence that the write had not happened and dispatch it again. The change records an interruption marker so the recovery ledger and interruption budget can handle the unresolved call.
The runtime's record now preserves a question it cannot settle from the missing response alone. A request can reach another service before the calling process learns its result. The caller's interrupted wait and the destination's work are separate parts of the same attempted action.
For an operator, the relevant question is therefore smaller than whether the whole agent run failed. Ask whether the particular write took effect. A run may stop while an earlier file creation succeeded, a later notification remains unsent, and the current ticket request is unresolved. Restarting the entire job without separating those actions can turn one uncertain step into several unnecessary repeats.
The release does not establish a universal recovery interface for every deployment. If your host exposes a run history, tool record or recovery view, use it to identify the attempted operation. If it does not, ask the person maintaining the integration how they inspect an interrupted write. An error banner by itself is too little evidence for an automatic resend policy.
 View image detail
Find the attempted action before inspecting its result
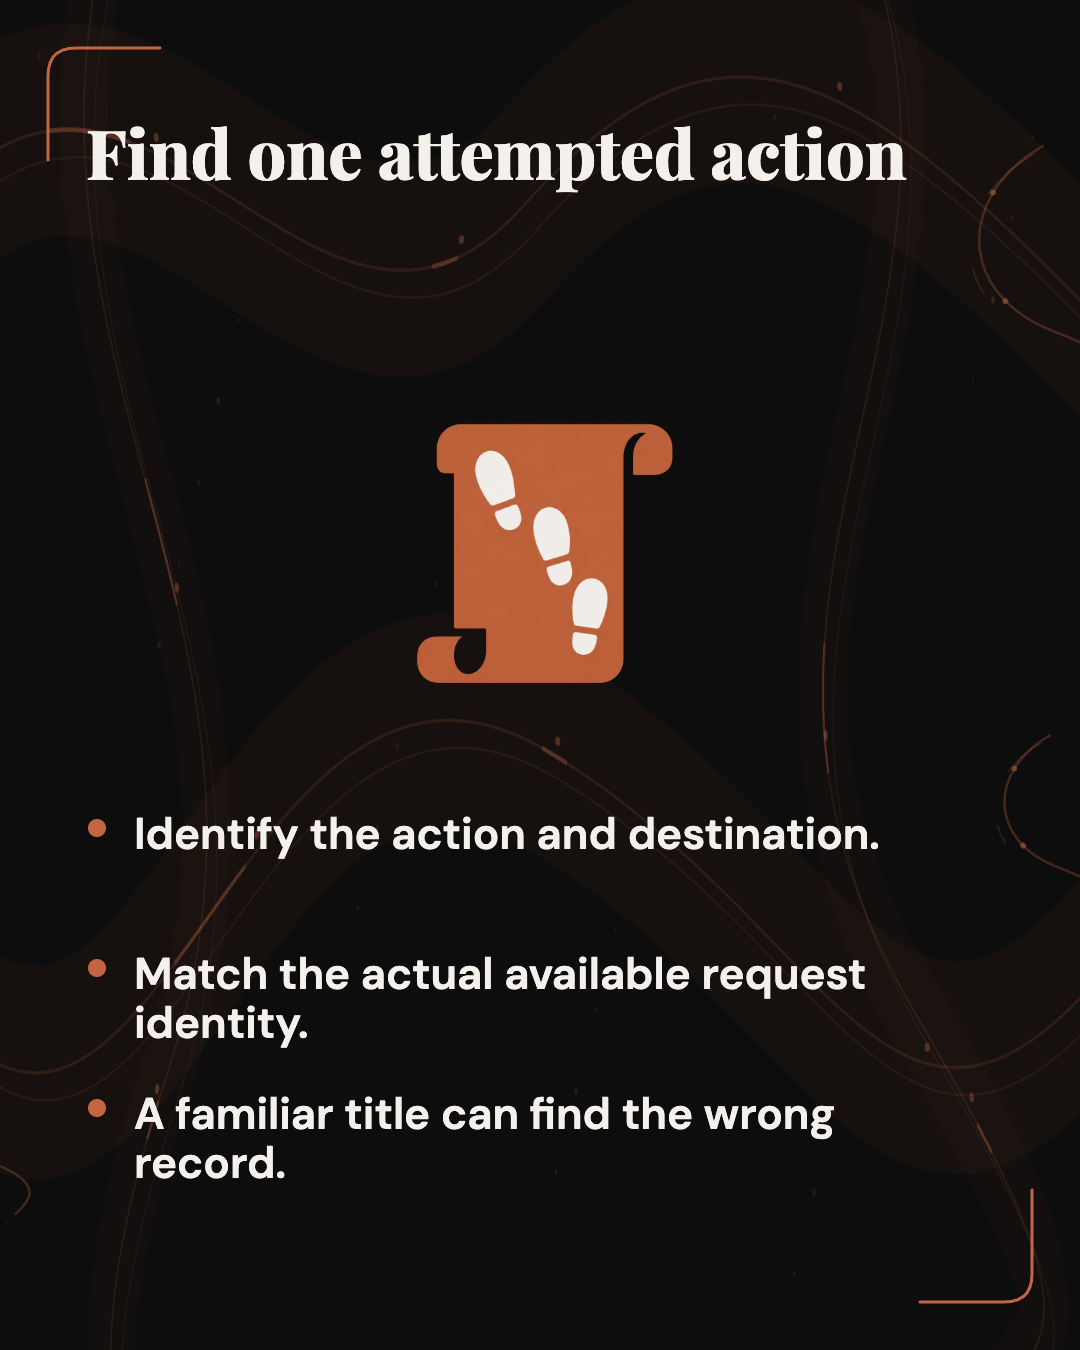
Start with the smallest action that could have changed something. In the hypothetical support workflow, that is creating one ticket, not completing the entire customer response. Record the intended destination, the ticket subject, the relevant account and the identity of the request if the integration supplies one. You are building a search target, not declaring success.
This step matters when an agent does several similar things. Two tickets can have the same subject for legitimate reasons. A project name can appear in several workspaces. A file may already exist because an earlier run created it. Searching only for a familiar title can find the wrong object and persuade someone to resume from a false starting point.
Use the identifiers actually available in the integration. These might include a returned resource identifier, a client request identifier, a recorded tool call or a destination audit event. Do not assume that an Agent-Native run identifier is automatically stored by the external service. The connection between the two records has to exist before it can help you reconcile them.
A useful operator note would say: this run attempted to create this ticket in this workspace, using this request identity, during this interval. That note can guide a targeted check without copying unrelated customer information into another tool. For a disposable evaluation, use invented names and a test workspace so the same inspection can be repeated safely.
If the integration provides none of those connections, the gap is part of the adoption decision. An opaque write path leaves the next operator with a recovery job they may not be able to complete. Improving that record can be more useful than asking the model to explain an error it cannot actually resolve.
 View image detail
Separate confirmed effects from unresolved outcomes
After identifying the action, sort the evidence into what it actually establishes. A destination record tied to the attempted request may establish that the ticket exists. A destination response that reliably rejects that exact operation may establish that it did not take effect. An empty search result can leave the question open if the search is incomplete or the record is not yet visible.
Those distinctions change the next action. If the intended ticket exists and its content is correct, another create request is unnecessary. If the evidence establishes that the write was rejected, a corrected attempt may be appropriate. If the outcome remains unresolved, keep it unresolved and decide who can inspect it further. Do not convert uncertainty into failure just because a retry button is easier to use.
Consider a hypothetical ticket that exists but contains the wrong account reference. Its existence answers whether a create operation happened. It does not answer whether the requested work is acceptable. Creating a second ticket could leave both the bad record and a duplicate notification. The corrective job might instead be an authorized edit or a review by the person responsible for that queue.
A reconciliation note should preserve those separate conclusions: effect found, quality still under review; effect reliably absent, corrected attempt permitted; or outcome unresolved, no new create request approved. The exact wording can be simpler in your team's interface. What matters is that someone can tell which claim is supported and which decision remains open.
Give this exception a real inspection path. A model can summarize available records, but its summary cannot supply a missing destination event. If the integration cannot retrieve sufficient evidence, the workflow needs a human or another supported inspection route rather than a more confident sentence.
 View image detail
A request identifier is not the same as retry safety
An identifier makes a request easier to recognize. Idempotency is a stronger contract: repeated attempts under the relevant identity do not create an additional effect. Writing a random identifier into a log does not make the receiving system enforce that contract.
Amazon's Builders' Library article on safe retries describes a caller-provided request identifier as an explicit statement of intent. It also explains why the service must coordinate recording that identifier with the operation it performs. This is useful background for evaluating an integration, not evidence that Agent-Native or every connected service implements Amazon's design.
For the hypothetical ticket workflow, inspect the destination's documented behavior before choosing a retry policy. Does the create operation accept a client identifier? What scope does it use to recognize duplicates? What happens if the same identifier arrives with different ticket contents? How long does the service retain the identity? Each answer can affect whether a delayed retry means the same job or a new one.
Changing an identifier just to get past a retry error is especially risky. It can tell the destination that this is a new operation while the operator still thinks they are finishing the old one. Conversely, reusing an old identifier after changing the destination or payload may no longer express the same intent. Treat the identity and the intended action together.
If the service does not expose a usable idempotent contract, the integration may still be useful. It simply needs a recovery policy suited to that limitation. A read-before-write check, an operator review or a separate compensating action can be part of a proposed design. None should be presented as a universal guarantee without checking the service's actual behavior.
 View image detail
Read the narrower retry promise carefully
The 0.187 release separately says review comment and reply submissions can be retried without duplicate comments or notifications. That is a specific operation family. It should not be silently extended to ticket creation, file uploads, CRM updates or a custom tool because they happen to sit inside the same agent workflow.
A practical action inventory can help. List the work the agent may perform, the destination of each write and the source that describes its retry behavior. Mark a documented operation separately from one whose behavior has not been checked. This is a proposed assessment method, not an Agent-Native feature advertised by the release.
In a small agency workflow, that inventory might distinguish preparing a draft from sending a client message. The draft can be inspected before delivery. The message crosses another boundary and may cause a notification even if the sender never sees a response. Treating both actions as one generic retry category hides the difference that matters to the client.
Review promises also need to include their side effects. Avoiding a duplicate comment while triggering the same notification again would be a different user experience from avoiding both. Builder.io explicitly names comments and notifications in this release claim. For another service, check what its own documentation includes instead of assuming the same scope.
Let routine work continue under its checked retry contract, and give uncertain consequential actions a clear owner. A blanket ban on retries would discard useful automation. A blanket promise that every write is safe would hide the exceptions. Classify the actions your team actually uses and make the decision at that level.
 View image detail
Plan an interruption test that can answer the right question
A useful proposed evaluation starts with disposable data and an action whose destination keeps an inspectable record. Pin the Agent-Native version under evaluation and identify the actual host, tool integration and destination. Those conditions should stay attached to any result because a later integration can behave differently.
Use a harmless write with a clearly identifiable request. Arrange one scenario in which the destination receives it but the agent stops before receiving the result. Arrange another in which the interruption occurs before the destination receives it. These are test goals, not instructions that the release guarantees your host can reproduce through a particular button or setting.
Compare the destination record with the runtime's account of the call. Did the host preserve the distinction between an interruption and a completed result? What did the resumed workflow attempt next? Could the reviewer identify the original action? Did any additional effect occur? Record what you observed rather than inferring the outcome from the last message in the chat.
Keep the result questions separate. The destination receiving one request is different from producing one correct resource. The agent avoiding an immediate redispatch is different from never duplicating work under every failure. A small controlled evaluation can establish behavior for that test setup without supporting a universal reliability claim.
If you cannot arrange a known interruption point or inspect the destination's records, record the test as incomplete. A random disconnect with no visibility into when the request arrived may be realistic, but it can be difficult to interpret. Use it as another scenario after the controlled case, not as the only basis for declaring the recovery path safe.
 View image detail
Check what a resumed workflow is allowed to do
Recovery can continue a workflow whose authority was granted earlier. That makes it important to check both what happened and what is permitted next. An old instruction to prepare a ticket does not automatically settle whether the agent should now notify a customer, edit an existing record or issue another create request.
The same 0.187 release includes a separate browser-approval change. It says approval information reaches the resumed run, with the continuation kept in the app chat that owns the paused run in the named embedded contexts. The original approval-routing change provides implementation context. Approval delivery and the outcome of an interrupted external write remain different questions.
For an operator, inspect the pending action the application presents. Confirm the target, the action and the account scope before allowing it. If the recovered job has changed, ask the integration owner how it represents that change and whether another review is needed. Do not assume a reassuring label in the chat establishes the full permission boundary.
A hypothetical ticket workflow illustrates the difference. A create request can have an unknown outcome even though the operator legitimately approved it. If the ticket is found later, the next useful action might be reading it. Editing its content or notifying someone is another action to evaluate. Preserving the earlier grant should not be used as evidence that all later actions were reviewed.
The broader Rise guide to agent authority develops that decision: decide which work may proceed, which exceptions require review and what evidence will support expansion. Here the exception is concrete. An interrupted write needs an outcome decision before the workflow chooses another consequential action.
 View image detail
Make the recovery handoff usable for another person
An exception can outlast the person who started the run. The next operator should not need to reconstruct the entire conversation to understand a single unresolved write. Prepare a concise handoff containing the intended action, the destination evidence examined, the current conclusion and the decision that still needs an owner.
Avoid filling the note with every tool response. A long log can bury the one identifier that connects the attempted write to a destination record. Link to the retained evidence where access permits and keep the summary focused on the recovery decision. Protect the same customer and account information you would protect during the original job.
Give the note a stopping condition. For example, in the hypothetical queue, another create request remains on hold until the reviewer can establish whether the original ticket exists or verify a supported retry contract. That is clearer than asking someone to look into an error with no stated consequence for what the agent may do next.
This handoff also helps separate a recovered job from a changed request. If the operator decides that the client needs a different ticket, record that new intent rather than hiding it inside a retry of the old one. The action identity, payload and authority should describe the same job. Otherwise the records may be individually accurate while the story connecting them is wrong.
The point of delegation is to give attention back to work that deserves it. Recovery should make the exception easier to understand, not require a human to watch every tool call forever. A targeted record and a specific decision can let the rest of the workflow remain automatic without pretending an unknown outcome is already settled.
 View image detail
Decide which workflow to evaluate first
Start with an existing task whose interrupted write would matter and whose destination can be inspected. A disposable ticket, a draft record or a test file can expose the recovery question without sending a real client message. Choose the action because its effect is understandable, not because a demo produces an impressive chat transcript.
Before that evaluation, confirm which Agent-Native package version your application actually uses. The historical 0.187 release is the subject of this article. A later release, a different host or a changed tool wrapper needs its own check. A repository announcement does not prove that a particular hosted application has adopted the change.
Keep a short decision record after the test. Describe the failure boundary, the destination effect and what the resumed workflow did. If the evidence supports automatic recovery for that operation, document its scope. If an uncertain outcome still requires review, make that review part of the normal workflow rather than treating it as an embarrassing exception.
The useful improvement in 0.187 is preserving uncertainty at the point where an automatic retry could matter. Recovery can inspect the write instead of treating silence as permission to do it again. For your own automation, choose one consequential action and establish how you would learn whether it already happened. That answer is the foundation for a retry policy worth trusting.
The same release also changes how embedded tool approvals return to a waiting run. The companion guide to app-chat approval routing examines that developer handoff. Delivering a valid approval and establishing whether an external write already happened remain separate questions.
Checked for this article
Sources
Keep going
Related notes.
Automation and Agents
Tencent Octop 1.0: A Self-Hosted AI Assistant for Small Teams?
Octop combines a self-hosted dashboard, agents, chat channels, connectors, coding tools and schedules. Here is how a small team can decide whether that consolidation fits.
Read the article
Automation and Agents
Inside Codex Alpha 10: Incremental Tool Catalogs and Code Mode MCP
How Codex Alpha 10 tracks changed tool declarations in Responses Lite and keeps Code Mode MCP resource helpers available, with the source and access limits.
Read the article
Automation and Agents
Agent-Native 0.187: Where Should Tool Approvals Resume?
A source-based review of how embedded app approvals reach their paused run, with proposed checks for the bridge, message route and receiving action.
Read the article