Automation and Agents
Strands Decider 2B: Validate Confidence Before Automating Decisions
A confidence score cannot set your routing policy. Reviewed cases can show which mistakes an automatic rule would allow and how much work it would send to people.
On this page
- Define the action that a score would control
- Collect cases that represent the decision
- Give reviewers a rule they can apply
- Run a shadow comparison with separate records for model and policy
- Examine confidence on the traffic that would use it
- Compare candidate rules by admitted mistakes and fallback load
- Compare the whole route with the current workflow
- Recheck the rule when the work changes
Imagine a customer reports a failed payout. An agent proposes sending the message to billing, and Strands Decider 2B selects that queue with a confidence score. Should the case move there automatically?
That depends on the action the score would trigger. The customer might also be locked out of an account. Billing might own the payout problem but need account support before it can investigate. A wrong assignment might cause a quick handoff in one case and a serious delay in another. The score alone cannot tell an operator which consequence applies or whether anyone can handle the cases held for review.
Strands’ announcement displays a publication date of October 1, 2026, without a time or timezone. It introduces Decider 2B as a model that selects supplied options or scores a supplied scale. The public repository captured October 3, 2026 describes choice, yes/no, and ordered-score questions. None of those formats supplies an organization’s action policy.
The useful test is whether a proposed rule makes acceptable decisions on your own reviewed cases, holds the cases that need attention, and sends a manageable amount of work to a real fallback. Define the action first. Then collect cases, run the candidate route without authority to act, examine errors across score ranges, and compare the whole route with the existing one. This is a proposed evaluation method; no product or customer trial was performed for this article.
Key takeaways
- Write down exactly what an automatic answer may do. Evidence for assigning an investigation owner does not authorize an account change or tool call.
- Check confidence against representative, reviewed traffic. The v19 model card limits its established confidence bands to held-out short classification tasks.
- Compare candidate rules by the consequential mistakes they would allow and the review work they would create. If the evidence cannot support automatic action, keep the current route.
Define the action that a score would control
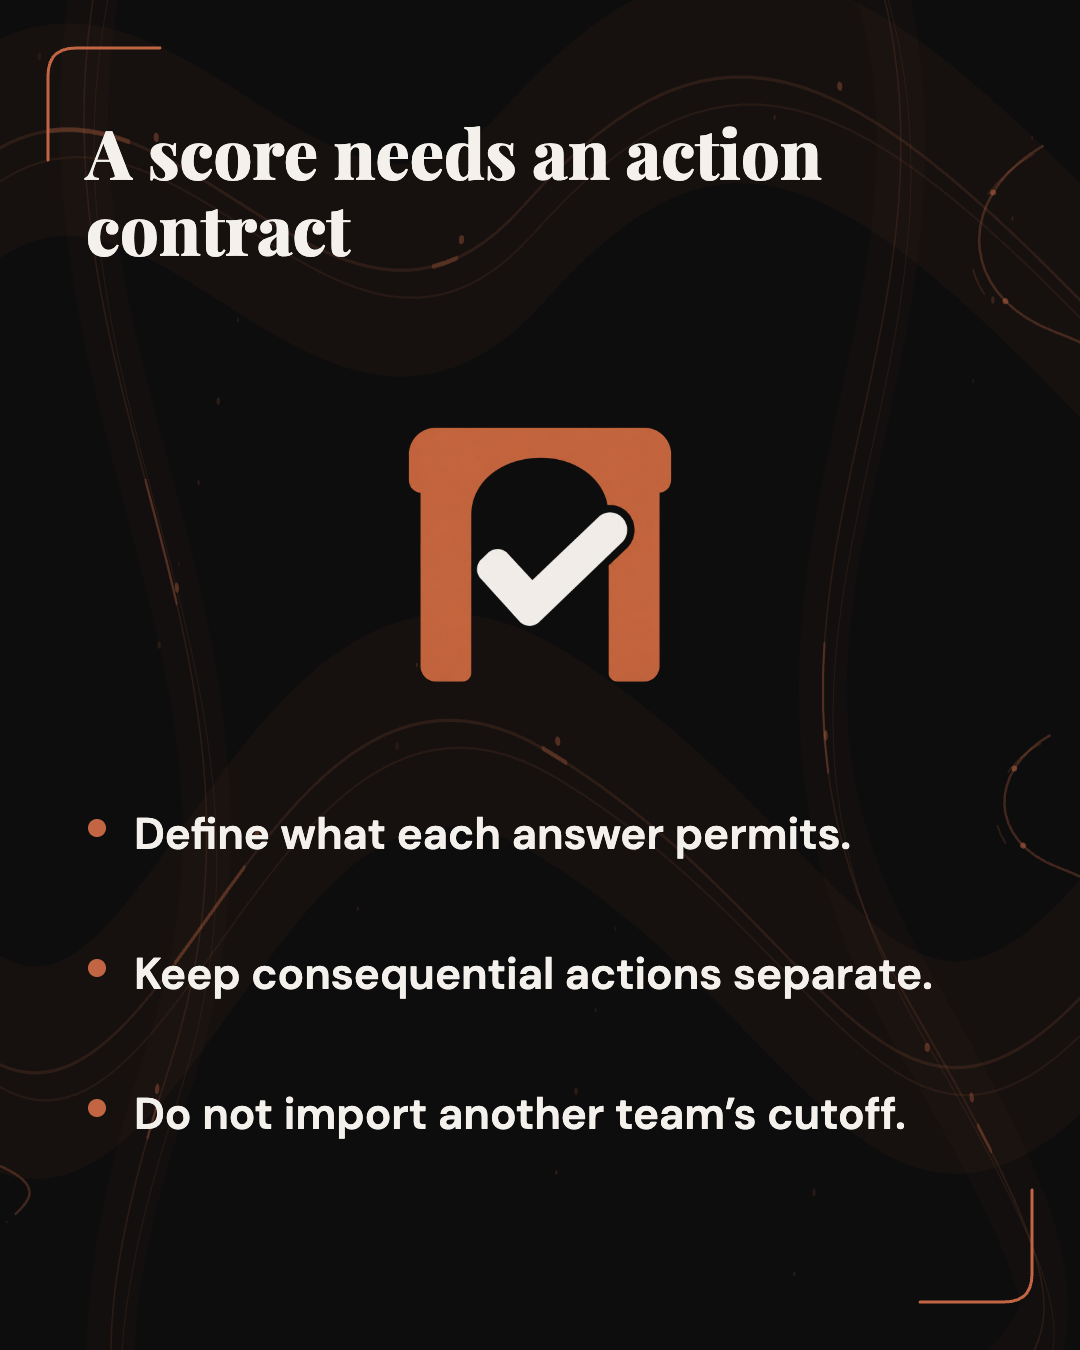
A threshold cannot make an unclear decision safe. Start with an action contract for the point where the model would be called. State the information available at that moment, the question and options sent to Decider, the action attached to each answer, and any cases that must go to a person regardless of score.
For a hypothetical payout router, the input might be the customer’s latest request and the agency’s written queue rules. The choices might be billing, account support, and ownership review. A billing answer would assign an investigation owner. It would not confirm an account identifier, approve a payout change, or permit a later tool call. Those actions depend on different facts and permissions.
This boundary determines what reviewers should judge. If the proposed action is queue assignment, ask whether the selected queue was appropriate under the rules and information available then. If the action changes a financial record, routing labels cannot serve as the reference answer. The proposed authority has changed, so the evaluation must change with it.
Name the owner of every destination. Ownership review is useful only if someone receives the case, knows why it was held, and can resolve it. Write down what happens when that queue reaches capacity. Also name who maintains the routing question when team responsibilities change. A model can continue returning an old option long after its meaning has changed.
The Strands repository documents a choice question for selecting among supplied options, a yes/no question, and an ordered-score question. Record the exact form used for the trial. Changing the question, option descriptions, or input midway changes the decision being evaluated. Keep a version of each alongside the results.
For this hypothetical agency, a message naming two accounts or correcting an earlier identifier might require review even if billing receives the highest score. A request combining failed payouts with lost access might follow a shared-ownership rule. These are proposed agency rules, not verified Decider capabilities. The evaluation must determine whether the surrounding workflow can identify such cases from the input it actually receives.
The contract may reveal that the organization has not settled who owns mixed requests. That is useful information. A routing trial cannot settle an ownership dispute simply by producing a confident label.
 View image detail
Collect cases that represent the decision
A score needs a defensible reference answer. Gather examples from traffic the organization is permitted to use and that the proposed route would actually receive. Preserve each input as it existed at the decision point. A fact discovered during a later investigation may explain the eventual resolution, but the earlier router did not have it.
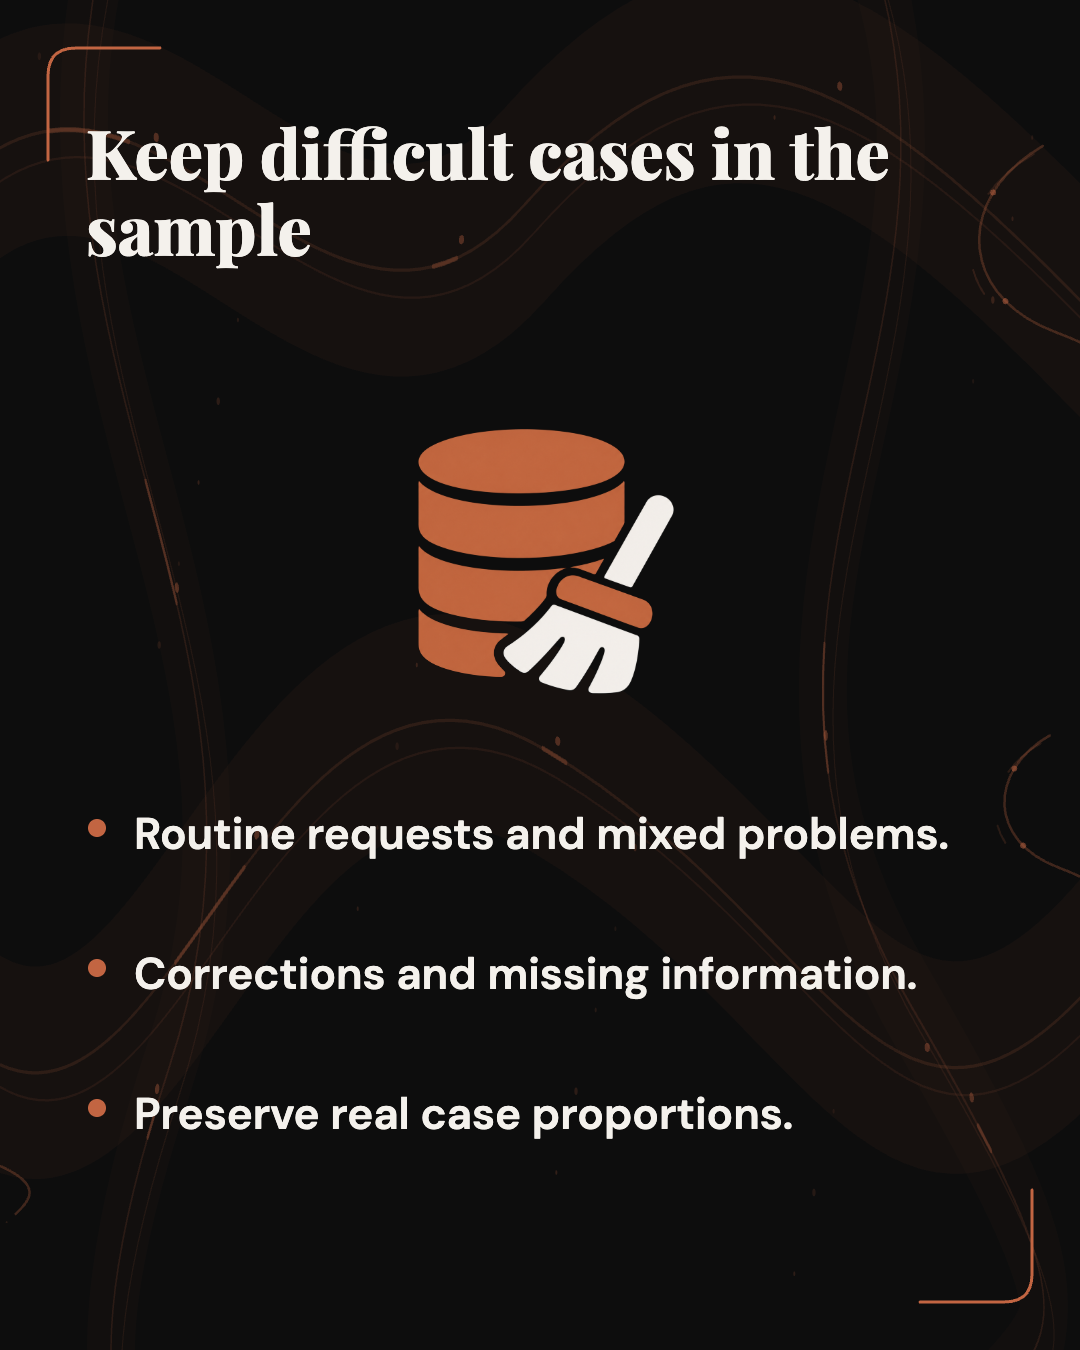
Use two collections for different purposes. A sample of ordinary traffic shows the mix the route would usually face and helps estimate likely fallback volume. A targeted collection of difficult cases probes failure modes that might be rare but consequential: two accounts, corrected identifiers, quoted numbers, combined billing and access requests, and messages with too little information. Report results separately. A deliberately enriched difficult-case set cannot estimate everyday review volume by itself.
Decide the unit of evaluation before collecting examples. If several messages belong to one customer issue, treating each as an independent case can make the sample appear larger and more varied than it is. If the route runs once when a request arrives, preserve that first decision opportunity. If it runs after every new message, record each opportunity and the information newly available then. The reference answer must match the decision point.
Do not select only cases with clean final outcomes. Ambiguous or incomplete requests are part of the traffic an automatic route would encounter. If reviewers cannot assign an owner from the available message, record that fact. It may point to a missing intake question or a decision being made too early.
Protect the customer’s information under the organization’s usual handling rules. Local execution, which the v19 model card documents as a use option, does not remove the need to control who can inspect cases or retain records. The proposal here is to use permitted, reviewable examples, not to copy an unrestricted customer archive into an experiment.
 View image detail
Give reviewers a rule they can apply
Provide responsible reviewers with the written ownership rules and the same information the proposed router would see. Ask each reviewer for a destination, a reason, and an indication when the information is insufficient. Record disagreements before adjudication. Otherwise, a disputed process rule can become a misleading model success or failure.
Consider a hypothetical message saying that a payout failed after the customer lost access to the account. One reviewer might choose billing because the payout is the immediate problem. Another might choose account support because access must be restored before billing can investigate. The team could assign one primary owner, establish a shared route, or send this pattern to ownership review. Until it settles that rule, a confident model answer has no stable reference to match.
Keep unresolved cases visible. They can test whether a mandatory-review condition catches ambiguity, even though they cannot fairly be counted as correct or incorrect against an unsettled queue label. Track how often this happens. Frequent disagreement may mean the organization needs a clearer rule before it needs a new router.
Record case types alongside reviewed destinations. Useful types for this example could include straightforward payout failure, payout plus access issue, account correction, multiple accounts, and insufficient facts. A strong aggregate match rate could hide weak handling of a consequential subgroup. Inspect both wrong assignments and clear cases sent unnecessarily to review; the latter consumes staff time even when no customer is misrouted.
Audit the reference set before using it. Check whether examples include facts the live route would not have, whether repeated issues from one customer dominate it, and whether a few standard templates crowd out unusual language. Set aside some reviewed cases while exploring candidate rules. Test a selected rule on those reserved cases; repeatedly adjusting it against the same examples can make its apparent success depend on cases already seen. If the reserved set is too small or omits an important pattern, state that limit.
 View image detail
Run a shadow comparison with separate records for model and policy
In a proposed shadow run, the existing workflow would remain responsible for real assignments. Decider would receive the permitted input and record what it would have selected. The team would compare that proposed answer with the reviewed destination and the existing path. The shadow route would take no automatic action.
Keep one record per decision opportunity. It should identify the input version or a controlled reference to it; question and option versions; model checkpoint; selected answer; relevant output fields; existing-path decision; reviewed destination or unresolved status; case type; and the route a proposed policy would have taken. If the trial concerns speed or cost, record timing and review effort at the same point in both paths.
Separate three things that are easy to blur: what the model returned, what the policy would permit, and what the existing workflow actually did. Suppose Decider prefers billing, but a separate rule holds every two-account message for ownership review. Store both the model’s answer and that policy outcome. The model should not receive credit for a fallback supplied by the policy, and the policy should not be reported as though it were the model’s selected option.
The repository’s examples show why output fields need names. Its sample choice output displays a selected option, a confidence figure, and option-level values. Its yes/no example displays a value leaning toward yes. Its ordered-score example displays a rubric position and a separate confidence figure. Keep each in its documented role. The captured sources do not establish that one cutoff has the same meaning across the three question types.
Write down the team’s unacceptable errors and mandatory-review categories before examining candidate scores. The team may revise a rule when it discovers a genuine flaw, but it should record the revision and evaluate the new version. Otherwise, an appealing score distribution can quietly redefine success after the fact.
 View image detail
Examine confidence on the traffic that would use it
The v19 model card says calibration was fitted on held-out short classification tasks, using one temperature per question primitive. It says the established confidence bands apply there only and advises measuring calibration on intended traffic before trusting a threshold. The card also identifies long, multi-step documents and transfer to unfamiliar yes/no questions or rubrics as weak spots.
For a payout router using choice questions, group reviewed cases into score ranges. For each range, report its case count, reviewed matches, mistakes, unresolved references, and case types. Ask whether higher-scored answers were more often correct on this workload. Then inspect whether a proposed boundary would separate cases suitable for automatic routing from those needing review.
Counts matter. A range containing only a few reviewed cases cannot support a precise claim about future mistakes. A high-scoring range dominated by routine payout messages might still contain errors on account corrections. Show the ordinary traffic sample and targeted difficult cases separately: one speaks more directly to likely operating volume, while the other helps expose specific failures. Neither alone settles the decision.
Inspect examples near any candidate cutoff. Two similar messages might fall on opposite sides because one contains a correction, the input is longer, or option wording changed. Compare the facts and actions for those cases. A numeric boundary is useful only if the cases it admits meet the team’s operating limits.
Correctness by score range is one question; the consequence of an error is another. A route might be more often correct at higher scores yet still admit a costly kind of misroute there. A lower-scored wrong assignment might be quickly reversible. Name the mistake and its likely effect instead of treating all mismatches as equal. For a tool-call check, distinguish an unsupported argument that would pass from a valid call that would be stopped.
Strands’ announcement illustrates a weather-tool check. A user asks about the weather without naming a city; an agent proposes a call with a city anyway. The example checks whether the arguments are grounded and whether the call is premature. Strands says its questions, threshold, and policy were chosen by hand. That illustration identifies a place to intervene. It supplies no measured reliability for another organization’s proposed calls.
The sources captured October 3, 2026, disagree on precise published evaluation figures. The repository reports 167 of 231 correct JevBench tasks at its stated 3,072-token evaluation window and says a saved 4,096-token version scored 168. Its performance table lists a Brier score of 0.342 for the stated evaluation. The model card reports 167 of 231 at both windows, with Brier scores of 0.349 at 3,072 tokens and 0.348 at 4,096. The captures do not reconcile these differences. None measures calibration on a reader’s payout queue, so none can set that queue’s cutoff.
 View image detail
Compare candidate rules by admitted mistakes and fallback load
Replay each candidate rule against the shadow records. Count cases that would proceed automatically, cases sent to fallback, and cases excluded by mandatory policy. Inspect the wrong answers that would take effect without review. Then ask whether the fallback owner could handle the cases the rule holds.
Use the same questions for every candidate:
- Which cases proceed automatically?: Evidence to record: Counts by case type and the exact condition admitting them
- Which wrong answers proceed?: Evidence to record: Reviewed examples and the consequences of their destinations
- Which valid answers are held?: Evidence to record: Clarification, delay, and review work created
- How much work reaches fallback?: Evidence to record: Ordinary-traffic volume and targeted difficult cases, reported separately
- Who resolves fallback?: Evidence to record: Named owner, context supplied, and available capacity
- Which cases remain excluded?: Evidence to record: Mandatory-review categories regardless of score
A permissive rule may reduce review work while allowing consequential misroutes. A restrictive rule may hold so many clear requests that ownership review becomes the main route. Compare each outcome with the existing workflow. A lower count of automatic mistakes is not enough if the rule moves work to an unstaffed queue.
Give fallback reviewers the facts needed to act. For a mixed payout and access request, that may include the relevant message, the candidate queue, and the reason the case was held. A bare score forces the reviewer to reconstruct the decision. Define what happens when capacity is exhausted: cases might remain in the existing path, wait under an authorized procedure, or follow another documented route. Count that delay and effort when comparing policies.
A rule may combine case type and score. The hypothetical agency might allow automatic assignment for straightforward payout failures while requiring ownership review whenever a message names multiple accounts. That design still needs evidence that the case-type condition works on the available input. A high billing score does not prove there is only one account.
Apply the selected rule to the reserved reviewed cases. Report any new consequential failure or fallback-capacity problem. If the evidence remains too thin for an automatic route, keep the existing route or refine the action contract. The captured Strands sources provide no numeric cutoff for this operating choice.
 View image detail
Compare the whole route with the current workflow
The Strands repository reports a 115-millisecond median per JevBench question on an RTX 3090 under WSL2 for v19, and a 153-millisecond warm median for tasks under 300 tokens on an M3 Pro. Those are vendor-reported measurements for specified tasks and hardware. The announcement’s latency graph caption refers to v18. None measures the time from a customer’s request to a usable owner in this hypothetical agency.
Measure that full interval in a proposed trial: obtaining the permitted input, serving the model, applying policy, waiting for clarification or review, and assigning an owner. Include compute demand, setup, maintenance, and human review effort. A fast model response can still produce a slow route if many cases wait for people. The captured sources provide no total-cost or outcome comparison for this workflow. They also provide no dated price schedule for a price comparison.
Compare both paths on the same decision opportunities. The existing route may already handle ordinary messages well, or it may create repeated handoffs. Those are empirical questions. Results could support limited automatic routing for defined cases, continued shadow operation, a revised ownership rule, or no adoption. Report which cases support the conclusion and which remain untested.
Before treating routing as an automation project, the Rise guide to deciding what to automate offers a broader check: examine input stability, judgment, failure consequences, and maintenance, then decide whether to simplify the work, automate it with review, or keep it human. That choice still matters if the proposed fallback creates more work than the current route.
Keep the authority narrow even after a successful routing evaluation. Evidence for assigning an investigation owner does not validate a later tool call or account change. Each consequential decision needs its own contract, reviewed cases, error analysis, and fallback.
 View image detail
Recheck the rule when the work changes
A threshold evaluated on one traffic mix belongs to that mix. Queue ownership, customer wording, conversation length, option descriptions, downstream actions, and review capacity can change. Name an owner who can notice those changes and return the candidate route to shadow mode or the existing path when its evaluated conditions no longer hold.
Keep question, checkpoint, and policy versions with decision records. Review fresh cases from changed traffic, including the difficult categories that mattered during the first evaluation. Recheck score ranges, consequential errors, and fallback volume. If an option now points to a different team or permits a different action, earlier routing results no longer answer the revised question.
 View image detail
At the October 3, 2026 capture, the v19 model card documented CPU, CUDA, and MPS options and described an HTTP server bound to 127.0.0.1 without authentication for local experiments. Making that service shared or public would require a separate access and security design. A successful routing evaluation would not supply one. Installation, download access during an actual run, and operation were not tested for this article. The separate Qwen base-weight terms were not checked.
 View image detail
Start with the action contract and cases responsible reviewers can judge. Let those cases show which mistakes a proposed rule would permit and how much work it would send to fallback. If no rule meets the team’s limits, keep the current route. The score can still inform a reviewer without deciding the case automatically.
Checked for this article
Sources
Keep going
Related notes.
Automation and Agents
Strands Decider 2B: Which Agent Decisions Are Worth Handling Locally?
Strands Decider 2B selects supplied options locally. Use five questions and three worked cases to decide which agent choice merits a contained trial.
Read the article
Automation and Agents
What Does Anthropic’s 26% AI-Led Research Figure Measure?
Anthropic says Claude led 26% of its measured AI R&D work in August 2026. The figure depends on task ratings and staff-time weights; here is how to read it.
Read the article
Automation and Agents
AI Agent Oversight: What to Check Before Giving an Agent Authority
Use Anthropic’s scoped oversight measurements to ask what an agent can change, when people review problems, and what evidence supports wider permission.
Read the article